The Sovereign Neocloud for Ultra Low-Latency Inference and Agentic AI.

Lower AI cost through complexity routing.

Get started
Governance

Sovereign by design

EU data residency and governance enforced in routing, not promised in contracts.

Performance

Ultra Low-Latency

Inference placed closer to users and applications.

Energy

Grid-supportive by design

Compute runs as a flexible, steerable load that generic AI gateways do not offer.

The Architecture

One platform. Three classes of sites.

The orchestration platform is the constant; the sites are interchangeable substrate. From energy sites to household PV and battery systems, every deployment runs the same software and fills one capacity pool.

Orchestration Layer

The orchestration platform unifies every node into one intelligent network: per-request matching to site, GPU and model, sovereignty policy, energy-aware load management and commercial APIs. This layer is the company’s core asset and the subject of its patent filings.

  • Sovereign AI
  • Low-Latency
  • Energy-Integrated
  • Unified PlatformOne platform. Three classes of sites.
  • Compute OrchestrationRight workload, right location
  • Security & SovereigntyEU data residency by design
  • CommercializationCapacity marketplace & APIs

Standardised units the platform runs on

Specified by CYANIS™, built and financed with partners: standardised deployment units in three sizes, so capacity is added as a repeatable unit rather than a construction project.

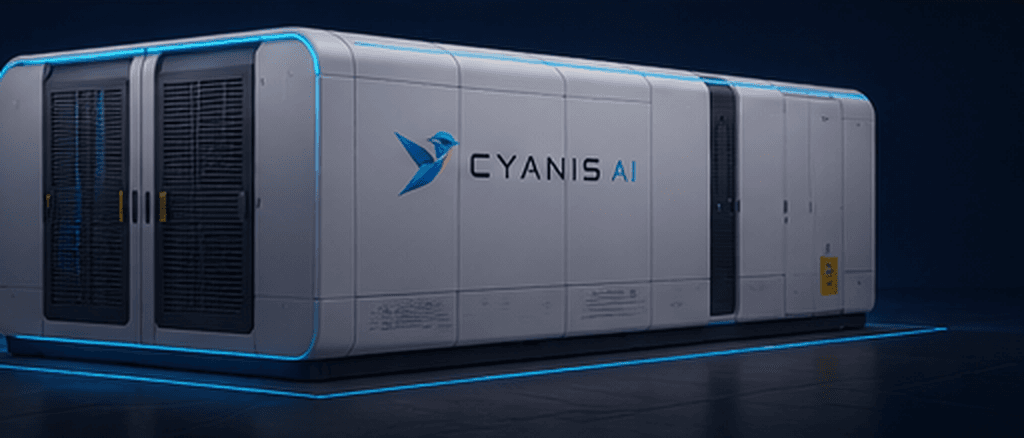
Energy site compute unit
Energy Site Unit
MW+
Prefabricated, containerised pod
Grid-integrated
GW-scale and beyond
Industrial compute unit
Industrial Unit
100 kW+
With heat extraction
Scalable
Resilient and local
Rapid install
Household compute unit
Household Unit
kW+
Plug and play
Behind the meter or grid-supplied
Distributed AI Compute Infrastructure
Residential, Commercial & Enterprise
One platform. Infinite scale.
EU Data ResidencyUltra Low-LatencyBuilt for AgentsOne API, One SLAGrid-Supportive by DesignElastic Multi-Node Scale-OutPatent-Pending OrchestrationDeployment in MonthsInfinite ScaleMW to GW ScaleSovereign AIGreen ComputeAgentic AIAgentLow-LatencyEU Data ResidencyUltra Low-LatencyBuilt for AgentsOne API, One SLAGrid-Supportive by DesignElastic Multi-Node Scale-OutPatent-Pending OrchestrationDeployment in MonthsInfinite ScaleMW to GW ScaleSovereign AIGreen ComputeAgentic AIAgentLow-Latency
How it works

From request to revenue.

Send an AI workload to the platform, or bring a site where it can run.
For compute customers

From request to response

Start building
  1. Connect

    Send requests through the CYANIS API or reserve dedicated capacity.

  2. Route

    The platform selects a capable model and site within your policy.

  3. Run

    Get a response under one SLA, with per-use or reserved pricing.

For site and energy partners

From site to revenue

Bring your site
  1. Qualify

    Qualify power, grid access and connectivity.

  2. Deploy

    Deploy standard units with integration partners.

  3. Earn

    Host compute as a flexible, grid-supportive load.

Why Cyanis

Three principles guide every deployment.

Sovereignty, latency and energy-aware placement shape the platform.

Sovereign AI

Enforce EU data residency through routing policy, not contract promises.

Ultra-Low Latency

Route each request to the nearest capable site and the smallest capable model.

Software-Defined Scale

Add repeatable capacity at powered sites. Tested scaling efficiency stays above 96% as capacity doubles.

Energy-linked infrastructure

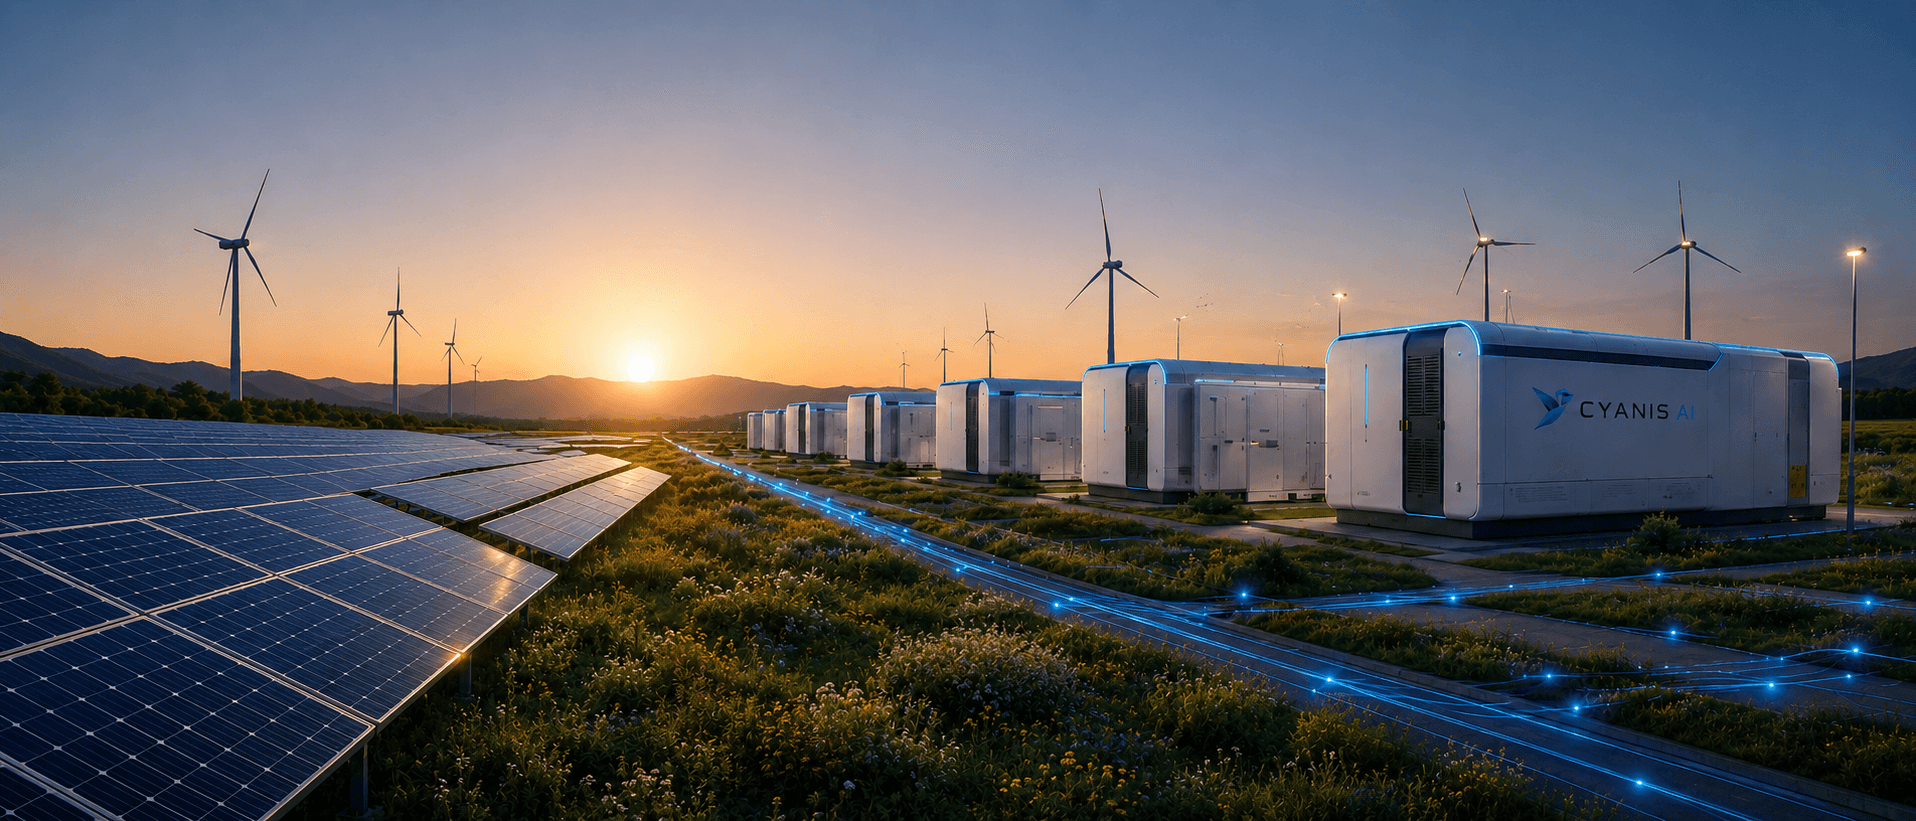
Deploy anywhere.
Compute everywhere.

Across distributed energy and infrastructure sites, from dispatchable power to storage.

Partner on a site
Become a partner

Your next step
starts here.

Tell us what you're building. Select your partner type and share your site, capacity or compute requirements.

Partner with Cyanis

Choose your partner type to get started.

Let's talk

Have questions?
We're here.

For general enquiries, reach out to our team directly.

info@cyanis.ai